SEOUL, November 02 (AJP) - South Korean computer scientists have found a way to teach existing artificial intelligence models specialist skills in as little as a third of the usual time, by choosing their training data more carefully rather than adding more of the costly chips that run the work.
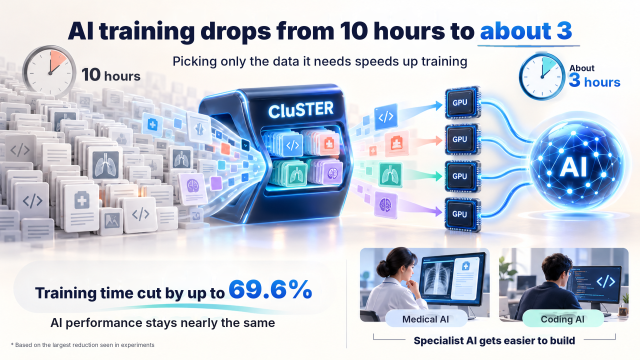
A team at the Korea Advanced Institute of Science and Technology (KAIST) said Monday that its method, called CluSTER, trained a model on medical question-and-answer data using about 31 percent of the full dataset. Training time fell by 69.6 percent, with only a small drop in accuracy compared with training on all of the data.
The work targets a step known as fine-tuning. Large language models, the technology behind AI chatbots, first learn broad general knowledge. To make one useful for writing code or answering medical questions, developers train it further on examples from that field, such as programming tasks with their solutions or patient questions paired with answers.
That extra training takes heavy computation, so the work is usually split across several graphics processing units (GPUs), the chips that carry out the calculations AI training requires. Each GPU processes its own share of the examples, and the results are combined to update a single model.
The researchers said the waste lies in how that data is handed out. Training sets for a given field tend to repeat themselves, with some types of problem appearing far more often than others. When examples are divided at random, several GPUs can end up working through material that teaches the model the same lesson, while rarer but useful examples get too little attention.
CluSTER first estimates how each example would change the model during training and groups together examples that would push it in a similar direction. The grouping does not depend on topic or wording. KAIST compared it to teaching a child addition, where a problem about combining two apples with three and one about combining two pencils with three tell different stories but teach the same calculation.
The system then draws an equal number of examples from every group, favoring those that differ most from the group's typical member so the model still sees a wide range of material. Each GPU receives a different group, which cuts down on duplicate work.
Trimming every group to the same size would distort the original mix of the data, so CluSTER weights each group's contribution to the model according to its share of the full dataset.
The team tested the method on three public datasets covering code generation and medical question answering, fine-tuning language models with about 7 billion and 13 billion parameters. Parameters are the internal values a model adjusts as it learns, and their number is a rough measure of its size. CluSTER was compared against five existing data-selection methods across eight benchmark tests.
Given the same amount of data, it recorded the highest average performance of any method tested. The 31 percent and 69.6 percent figures came from the medical question-answering tests. At that rate, a training job that took 10 hours would finish in about three.
KAIST said the selection step itself also ran faster than those of earlier data-selection methods, so the savings were not eaten up by the time spent preparing the data.
Most of the experiments ran on four GPUs, and the team said the method also outperformed existing approaches on eight. Lee Jae-gil, a professor in KAIST's School of Computing who led the research, said the gains came from the data rather than the hardware.
"To raise the efficiency of AI training, it is important not only to use more GPUs but also to choose smartly which data to train on," Lee said, adding that the work matters because it "can reduce the training burden of large AI models by using existing GPU resources more efficiently."
KAIST said the method could help companies and research institutes cut the time and GPU costs of building AI for specific jobs, such as customer service tailored to one company, coding assistance, or tools that help medical staff look up information.
The results so far come from a narrow set of conditions. The tests covered models of up to 13 billion parameters on four or eight GPUs, and KAIST did not report how the method performs on larger models or larger GPU clusters. It also did not give the size of the accuracy drop or the time savings in the coding tests, and the method has not yet been used outside the laboratory.
Kim Hyun-jin, a doctoral student in KAIST's School of Computing, was the paper's first author, with Lee as corresponding author. Nam Young-eun, a KAIST graduate now a postdoctoral researcher at the University of Toronto, and Han Jae-min and Choi Won-hyeok, master's students at KAIST's Graduate School of Data Science, were co-authors.
The paper was presented in October at EMNLP 2026, the Conference on Empirical Methods in Natural Language Processing, one of the main international meetings in the field, held this year in Budapest.
[Reference Information]
Journal/Source: EMNLP 2026 (Conference on Empirical Methods in Natural Language Processing)
Title: Clustering-Based Balanced Sampling and Allocation with Data Parallelism for High-Performance Fine-Tuning
Link/DOI: https://arxiv.org/abs/2609.12584
Copyright ⓒ Aju Press All rights reserved.